When we say “AI,” we almost always mean the same thing
Artificial intelligence | Topics & Trends
This concern is valid. But it’s based on an assumption that isn’t always true: that AI must necessarily read and understand content to be useful. That’s not the case. There are AI systems that don’t read any text at all and still save time every day. We’ve built an example of this at Westernacher Solutions, and that’s exactly what this post is about.
The everyday problem: sorting things out before the real work begins
Government agencies, courts, and church administrations receive large volumes of documents every day: applications, copies of identification, certificates, and supporting documents. Before anyone can review their content, these documents must first be sorted.
That sounds trivial, but in practice it rarely is. After all, people who submit documents don’t always follow the guidelines: a label is missing, a mark is forgotten, or a page is mislabeled. The result: Documents end up on desks without clear classification and must be sorted manually before the actual substantive work can even begin. This takes time, delays processes, and ties up staff who are actually needed to review the content.
The obvious reaction: Why it’s risky in the public sector
The obvious idea is: “Then let an AI read the documents and sort them automatically.” But this is exactly where the problem begins—one that causes many organizations with strict data protection requirements to hesitate.
AI that reads the content of documents poses three typical risks:
- Sensitive training data: It typically requires real, personally identifiable information such as names, addresses, dates of birth, and ID numbers.
- On-the-fly processing: Even while in operation, it continuously processes this sensitive data.
- Biased results: It can make errors that systematically target certain groups, such as those with unusual names or special characters.
For organizations that must pay particular attention to data protection, legal certainty, and fairness, this is not an ideal starting point. And this is precisely where it’s worth questioning the assumption described at the beginning: Does the AI even need to read the documents?
The Solution: AI that recognizes documents by their form, not their content
We’ve chosen a different approach, and that’s the point of this post: Our AI doesn’t actually read the documents. Instead, it looks at what a document looks like.
An example from everyday life can help clarify this: If you walk past a coworker’s desk and see a stack of papers there, you can tell at a glance what kind of documents they are. An ID card looks different from a form, and a form looks different from a certificate. You don’t have to read a single word to tell. The shape, layout, and structure are enough.
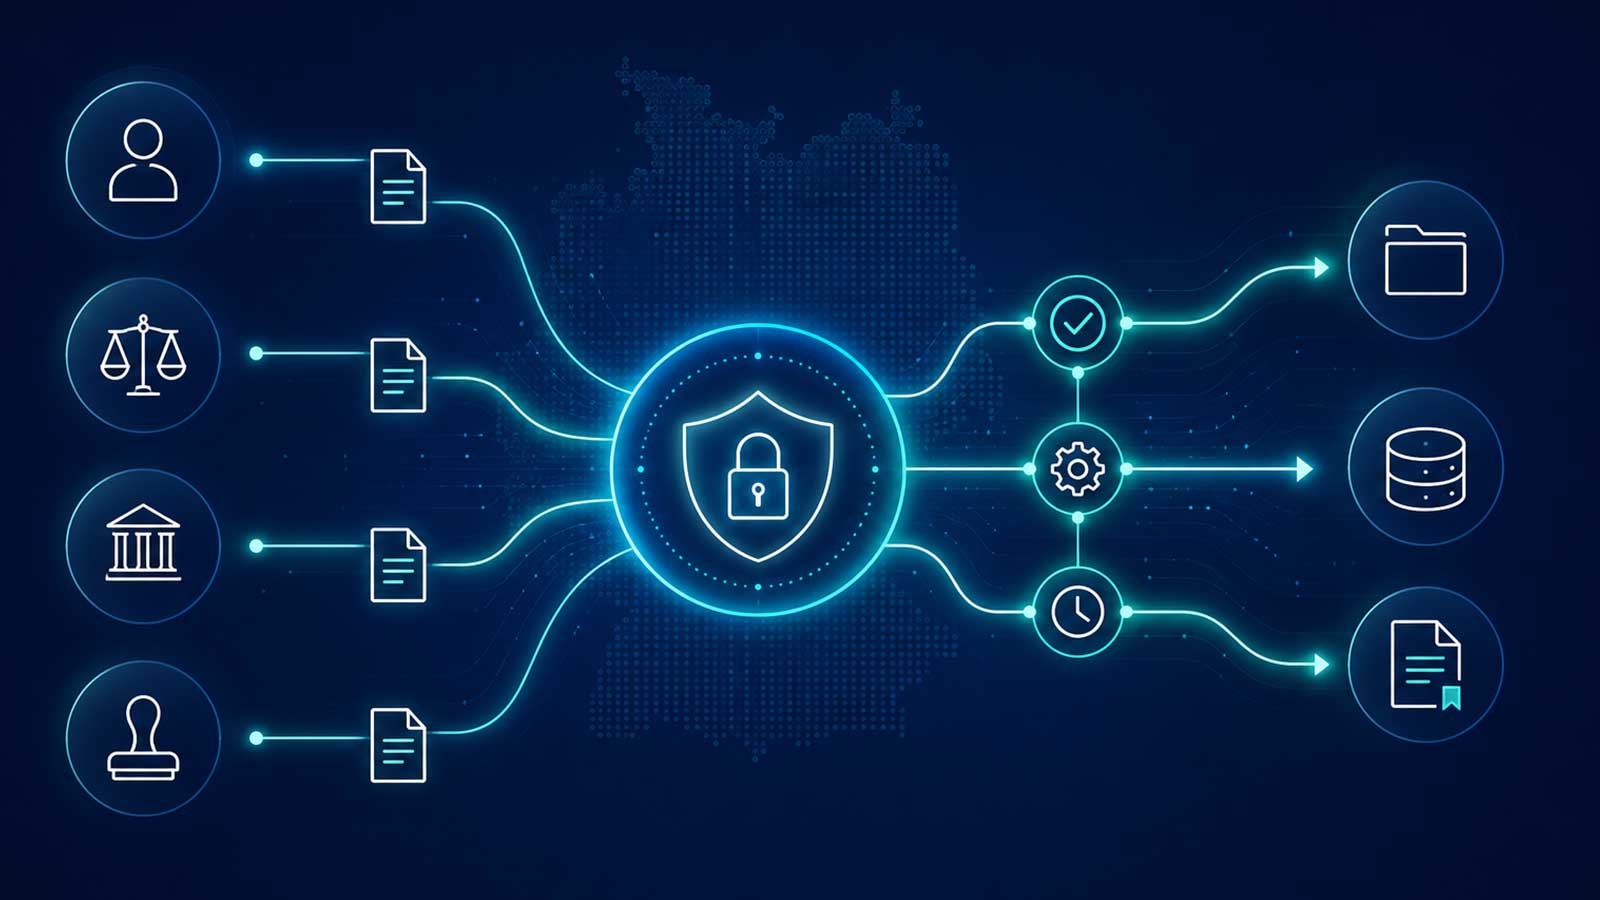
That’s exactly how our solution works. First, the document is converted into a black-and-white image. Then, the AI uses contrast to identify which areas are important for determining the document’s type: borders, fields, lines, stamps, signature areas, or typical document sections. It marks these areas in the image with boxes. This makes it clear how the AI determines the document type: not based on names or addresses, but on visible structures.
The result: Documents are automatically assigned to the correct category without the AI ever knowing who the person is or what information the document contains. Employees receive the assignment as a suggestion and can confirm or correct it with a single click. The final decision always rests with a human.

AI-powered document classification based on visual structures—without reading the content.
Why This Is More Than Just a Technical Detail
The fact that this AI is not a large language model is not a minor detail, but rather its key advantage. This directly results in concrete benefits for your organization:
- Less effort required for data protection: What isn’t read doesn’t need to be protected, documented, or legally safeguarded. Personal information simply plays no role in the classification process.
- Full control in-house: The solution runs locally in your IT environment. No data leaves your premises. This is a key component of digital sovereignty.
- Less bias: If you don’t read names, you can’t be thrown off by unusual ones. Classifying by shape is fairer because you don’t know the person at all.
- Faster processes: Less manual sorting means more time for the actual technical review.
It’s not the size that matters, but the problem
This use case is no accident. It illustrates how we work at Westernacher Solutions. We deliberately avoid jumping on every bandwagon. Just because large language models are currently dominating the AI landscape doesn’t mean they’re the right choice for every task. For us, the starting point isn’t the technology—it’s the problem: What exactly needs to be solved, and which solution fits the bill without handling more data than necessary?
That is exactly why, in this case, we decided against the obvious, “big” solution and opted for one that fits the use case while protecting personal data. It wasn’t the biggest AI that won—it was the right one.
We don’t develop these solutions without involving our customers. The most important part of our work happens through dialogue: We sit down with the people who work with these processes every day, understand their specific use cases, and use that to develop a solution that truly fits their organization—technically, legally, and in their day-to-day work. After all, AI that’s developed without taking users’ realities into account doesn’t help anyone.
This approach is particularly important for the public sector. Government agencies, courts, and church administrations bear a high level of responsibility for the data entrusted to them. They do not need technology that can do as much as possible, but rather solutions that do exactly what is necessary: transparent, data-minimal, and under their own control.
For us, therefore, the key question is never “Which AI is the biggest?” but rather, “Which AI is best suited for this problem, and who retains control over the data?” We ask this question together with our customers. And we build the solution that emerges from it.
Conclusion: The right AI addresses the problem, not the hype
The lesson to be learned from this use case is also the simplest one: AI doesn’t have to be big, all-knowing, or able to read text to be helpful. Sometimes the best solution is the one that deliberately does less—but does exactly the right thing.
This is an important message for the public sector. Not every task requires a large language model with all the associated data protection and oversight issues. For those seeking to solve a clearly defined problem—such as sorting documents—a specialized, autonomous AI is often a better, safer, and more transparent solution.
Westernacher Solutions supports public organizations in making precisely these decisions. The approach is not technology-driven, but rather responsibility-oriented. After all, the crucial question is never “Which AI is the biggest?” but rather: “Which AI is best suited to our problem, and who controls the data in the process?”
Frequently Asked Questions About Document Classification Without Text Recognition

Your contact person
Dr. Maria Börner
AI Competence Center Lead